Capability-Driven Multimodal Scaling Law

What transfers
from text to vision?

Capability Scaling Laws and Transfer Dynamics for VLMs

Predict how a language backbone will learn from multimodal data—using its text capability and a planned training budget.

Capability-driven prediction 01 — 03
01 / OBSERVE

Text capability S

What the language model knows

02 / PLAN

Multimodal data D

How much it will learn from

transfer + absorption
03 / PREDICT

A learning curve,
before training.

Across scales. Across families.

PerformanceData budget →
Conceptual illustration · see the measured results below
Ziran Li1*Qiang Wang2*Zhengyu Chen1Shanglin Lei1Borun Chen1Jingang Wang1Xunliang Cai1
1 Meituan2 Tsinghua University* Equal contributionarXiv:2608.00013 ↗
34Language backbones
7Model families
150+VLMs trained
72BScale extrapolation
01A preliminary observation

Text capability and multimodal performance move together.

Stronger text capability tends to accompany
stronger multimodal performance.

As an initial observation, we examine 17 LLM–VLM pairs from the OpenCompass leaderboard. Language backbones with higher text benchmark scores tend to have VLM counterparts with higher multimodal scores, revealing a positive correlation between the two capabilities.

This observation motivates our central question: can textual capability help us predict multimodal performance? The correlation alone does not explain how much capability transfers or how a backbone learns from additional multimodal data. Our scaling law models these two effects jointly.
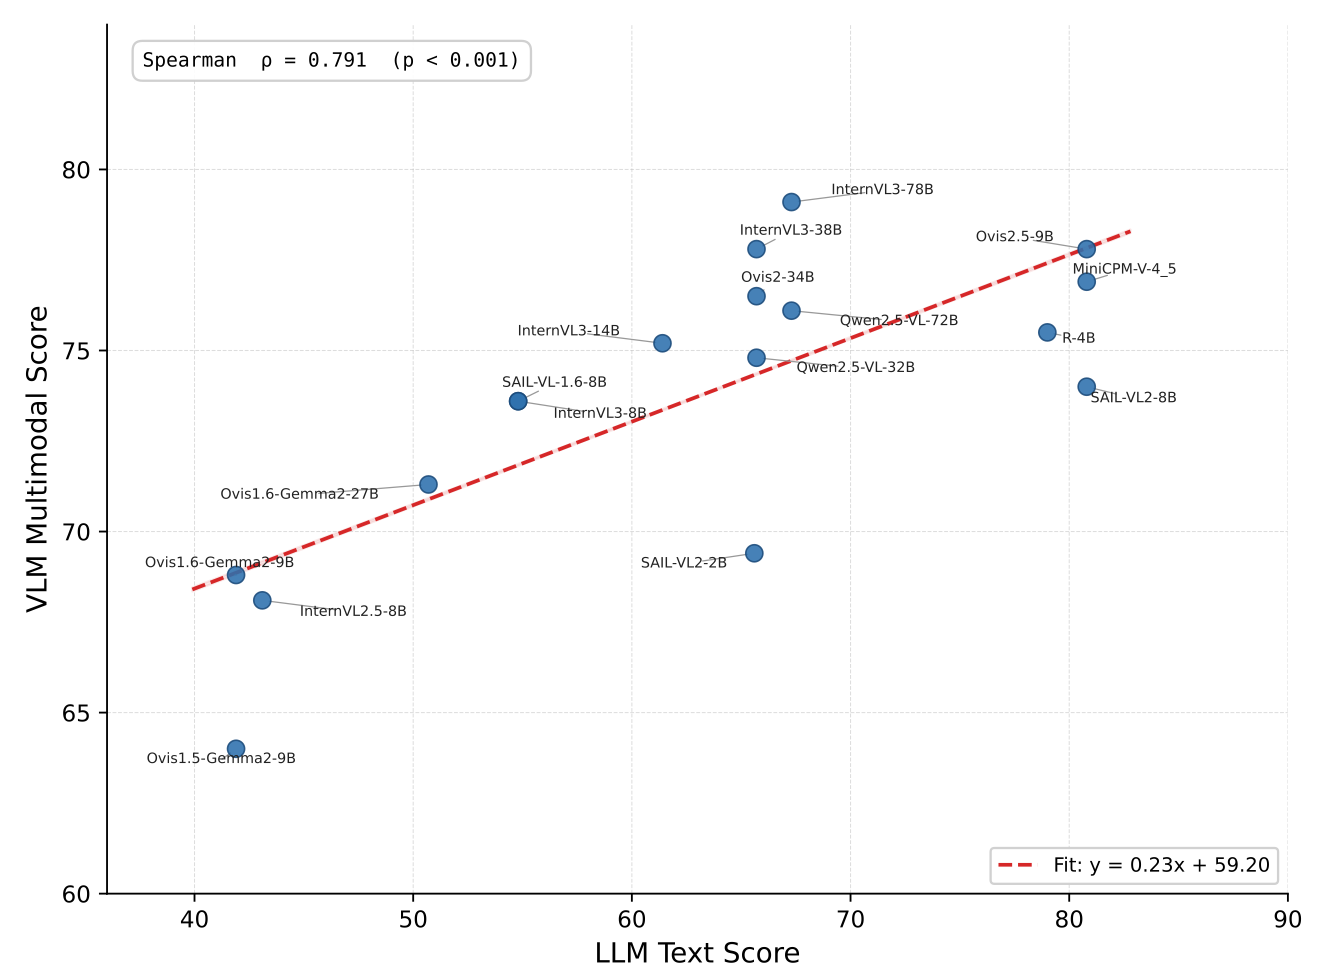
Text scores of 17 language backbones plotted against their corresponding VLM multimodal scores, showing a strong positive correlation with Spearman rho of 0.791 and p less than 0.001.
Figure 6 · Preliminary evidence of a positive correlation An initial analysis of 17 LLM–VLM pairs from the OpenCompass leaderboard shows a positive association between text and multimodal scores (Spearman ρ = 0.791, p < 0.001; Appendix A.1). Click the figure to enlarge ↗
02The method

Transfer sets the start. Absorption shapes the slope.

One capability score and one data budget predict the multimodal accuracy trajectory.

P(S,Dmm)=A^S⏟transfer+(B0−BmS)ln⁡Dmm⏟data absorption+P0P(S,D_{\mathrm{mm}})=\underbrace{\hat{A}S}_{\text{transfer}}+\underbrace{(B_0-B_mS)\ln D_{\mathrm{mm}}}_{\text{data absorption}}+P_0

S · Text capabilityA learned, unit-norm projection of PCA-compressed text benchmark scores.

B̂ = B₀ − BₘS · AbsorptionStronger textual priors reduce the marginal benefit of additional multimodal data.

P₀ · BaselineThe fitted intercept captures benchmark-specific baseline performance.

01

Measure

Evaluate the backbone on text benchmarks and center its scores.

02

Project

Compress with PCA (≥95% explained variance), then compute the learned capability score S.

03

Predict

Keep the fitted projection and coefficients fixed. Supply a data budget to obtain a learning curve.

During fitting, capability weights and scaling coefficients are learned jointly from observed VLM trajectories using Huber loss and a nonnegative-absorption penalty. At inference, only text scores and the planned token budget are needed. (§2, Appendix E)

Explore the mechanism · interactive prototype

Choose the evidence.
Inspect the fit.

Filter real checkpoints and see how the scaling coefficients and fitting error change.

34 backbones · 264 checkpoints32 fitting candidates + 2 original 72B holdouts
Fitting backbones32 / 32
Training checkpoints256
Training MAE1.2872%

Fitted vs. observed accuracy

Hover, focus, or click a checkpoint to inspect its fitted value.

40%50%60%70%-0.0500.050.10.150.20.25Observed multimodal accuracyÂS + B̂ ln DQwen2.5-72B-Instruct · S 0.821 · 12.58B · 64.39%Qwen2.5-72B-Instruct · S 0.821 · 25.17B · 64.81%Qwen2.5-72B-Instruct · S 0.821 · 37.75B · 65.04%Qwen2.5-72B-Instruct · S 0.821 · 50.33B · 65.02%Qwen2.5-72B · S 0.663 · 12.58B · 63.23%Qwen2.5-72B · S 0.663 · 25.17B · 63.69%Qwen2.5-72B · S 0.663 · 37.75B · 64.47%Qwen2.5-72B · S 0.663 · 50.33B · 64.84%Qwen3-0.6B · S -0.143 · 12.58B · 43.47%Qwen3-0.6B · S -0.143 · 25.17B · 44.24%Qwen3-0.6B · S -0.143 · 37.75B · 45.62%Qwen3-0.6B · S -0.143 · 50.33B · 46.46%Qwen3-0.6B · S -0.143 · 62.91B · 46.94%Qwen3-0.6B · S -0.143 · 75.50B · 47.27%Qwen3-0.6B · S -0.143 · 88.08B · 47.67%Qwen3-0.6B · S -0.143 · 100.66B · 47.88%Qwen3-0.6B-Base · S -0.273 · 12.58B · 43.79%Qwen3-0.6B-Base · S -0.273 · 25.17B · 44.25%Qwen3-0.6B-Base · S -0.273 · 37.75B · 45.10%Qwen3-0.6B-Base · S -0.273 · 50.33B · 45.90%Qwen3-0.6B-Base · S -0.273 · 62.91B · 46.56%Qwen3-0.6B-Base · S -0.273 · 75.50B · 46.96%Qwen3-0.6B-Base · S -0.273 · 88.08B · 47.17%Qwen3-0.6B-Base · S -0.273 · 100.66B · 47.18%Falcon3-1B-Instruct · S -0.334 · 12.58B · 39.25%Falcon3-1B-Instruct · S -0.334 · 25.17B · 39.68%Falcon3-1B-Instruct · S -0.334 · 37.75B · 40.72%Falcon3-1B-Instruct · S -0.334 · 50.33B · 41.33%Falcon3-1B-Instruct · S -0.334 · 62.91B · 41.89%Falcon3-1B-Instruct · S -0.334 · 75.50B · 42.33%Falcon3-1B-Instruct · S -0.334 · 88.08B · 42.40%Falcon3-1B-Instruct · S -0.334 · 100.66B · 42.49%Falcon3-1B-Base · S -0.357 · 12.58B · 39.16%Falcon3-1B-Base · S -0.357 · 25.17B · 39.21%Falcon3-1B-Base · S -0.357 · 37.75B · 39.94%Falcon3-1B-Base · S -0.357 · 50.33B · 40.47%Falcon3-1B-Base · S -0.357 · 62.91B · 41.77%Falcon3-1B-Base · S -0.357 · 75.50B · 42.30%Falcon3-1B-Base · S -0.357 · 88.08B · 42.19%Falcon3-1B-Base · S -0.357 · 100.66B · 41.69%Llama-3.2-1B-Instruct · S -0.309 · 12.58B · 41.91%Llama-3.2-1B-Instruct · S -0.309 · 25.17B · 42.34%Llama-3.2-1B-Instruct · S -0.309 · 37.75B · 43.23%Llama-3.2-1B-Instruct · S -0.309 · 50.33B · 43.46%Llama-3.2-1B-Instruct · S -0.309 · 62.91B · 43.55%Llama-3.2-1B-Instruct · S -0.309 · 75.50B · 43.56%Llama-3.2-1B-Instruct · S -0.309 · 88.08B · 44.23%Llama-3.2-1B-Instruct · S -0.309 · 100.66B · 44.62%Llama-3.2-1B · S -0.369 · 12.58B · 40.47%Llama-3.2-1B · S -0.369 · 25.17B · 41.22%Llama-3.2-1B · S -0.369 · 37.75B · 42.33%Llama-3.2-1B · S -0.369 · 50.33B · 42.89%Llama-3.2-1B · S -0.369 · 62.91B · 43.35%Llama-3.2-1B · S -0.369 · 75.50B · 43.92%Llama-3.2-1B · S -0.369 · 88.08B · 44.35%Llama-3.2-1B · S -0.369 · 100.66B · 44.48%Qwen3-1.7B · S 0.026 · 12.58B · 48.02%Qwen3-1.7B · S 0.026 · 25.17B · 48.12%Qwen3-1.7B · S 0.026 · 37.75B · 49.33%Qwen3-1.7B · S 0.026 · 50.33B · 49.97%Qwen3-1.7B · S 0.026 · 62.91B · 50.91%Qwen3-1.7B · S 0.026 · 75.50B · 51.02%Qwen3-1.7B · S 0.026 · 88.08B · 50.93%Qwen3-1.7B · S 0.026 · 100.66B · 50.81%Qwen3-1.7B-Base · S -0.069 · 12.58B · 46.06%Qwen3-1.7B-Base · S -0.069 · 25.17B · 46.38%Qwen3-1.7B-Base · S -0.069 · 37.75B · 47.73%Qwen3-1.7B-Base · S -0.069 · 50.33B · 48.09%Qwen3-1.7B-Base · S -0.069 · 62.91B · 48.58%Qwen3-1.7B-Base · S -0.069 · 75.50B · 48.42%Qwen3-1.7B-Base · S -0.069 · 88.08B · 48.44%Qwen3-1.7B-Base · S -0.069 · 100.66B · 48.41%gemma-2-2b-it · S -0.042 · 12.58B · 45.03%gemma-2-2b-it · S -0.042 · 25.17B · 44.98%gemma-2-2b-it · S -0.042 · 37.75B · 46.65%gemma-2-2b-it · S -0.042 · 50.33B · 47.93%gemma-2-2b-it · S -0.042 · 62.91B · 49.97%gemma-2-2b-it · S -0.042 · 75.50B · 50.32%gemma-2-2b-it · S -0.042 · 88.08B · 50.86%gemma-2-2b-it · S -0.042 · 100.66B · 50.81%gemma-2-2b · S -0.123 · 12.58B · 45.07%gemma-2-2b · S -0.123 · 25.17B · 46.04%gemma-2-2b · S -0.123 · 37.75B · 47.92%gemma-2-2b · S -0.123 · 50.33B · 48.64%gemma-2-2b · S -0.123 · 62.91B · 49.43%gemma-2-2b · S -0.123 · 75.50B · 49.70%gemma-2-2b · S -0.123 · 88.08B · 50.13%gemma-2-2b · S -0.123 · 100.66B · 50.03%Falcon3-3B-Instruct · S -0.120 · 12.58B · 46.16%Falcon3-3B-Instruct · S -0.120 · 25.17B · 46.52%Falcon3-3B-Instruct · S -0.120 · 37.75B · 47.27%Falcon3-3B-Instruct · S -0.120 · 50.33B · 47.65%Falcon3-3B-Instruct · S -0.120 · 62.91B · 48.13%Falcon3-3B-Instruct · S -0.120 · 75.50B · 48.21%Falcon3-3B-Instruct · S -0.120 · 88.08B · 48.39%Falcon3-3B-Instruct · S -0.120 · 100.66B · 48.24%Falcon3-3B-Base · S -0.178 · 12.58B · 45.52%Falcon3-3B-Base · S -0.178 · 25.17B · 45.77%Falcon3-3B-Base · S -0.178 · 37.75B · 46.53%Falcon3-3B-Base · S -0.178 · 50.33B · 46.85%Falcon3-3B-Base · S -0.178 · 62.91B · 47.61%Falcon3-3B-Base · S -0.178 · 75.50B · 47.66%Falcon3-3B-Base · S -0.178 · 88.08B · 47.81%Falcon3-3B-Base · S -0.178 · 100.66B · 47.45%Llama-3.2-3B-Instruct · S -0.016 · 12.58B · 48.06%Llama-3.2-3B-Instruct · S -0.016 · 25.17B · 48.34%Llama-3.2-3B-Instruct · S -0.016 · 37.75B · 48.98%Llama-3.2-3B-Instruct · S -0.016 · 50.33B · 49.25%Llama-3.2-3B-Instruct · S -0.016 · 62.91B · 49.10%Llama-3.2-3B-Instruct · S -0.016 · 75.50B · 48.51%Llama-3.2-3B-Instruct · S -0.016 · 88.08B · 47.66%Llama-3.2-3B-Instruct · S -0.016 · 100.66B · 47.27%Llama-3.2-3B · S -0.130 · 12.58B · 46.73%Llama-3.2-3B · S -0.130 · 25.17B · 47.30%Llama-3.2-3B · S -0.130 · 37.75B · 48.75%Llama-3.2-3B · S -0.130 · 50.33B · 49.34%Llama-3.2-3B · S -0.130 · 62.91B · 50.20%Llama-3.2-3B · S -0.130 · 75.50B · 50.21%Llama-3.2-3B · S -0.130 · 88.08B · 50.08%Llama-3.2-3B · S -0.130 · 100.66B · 49.60%Qwen3-4B · S 0.237 · 12.58B · 50.15%Qwen3-4B · S 0.237 · 25.17B · 49.49%Qwen3-4B · S 0.237 · 37.75B · 49.96%Qwen3-4B · S 0.237 · 50.33B · 50.15%Qwen3-4B · S 0.237 · 62.91B · 50.95%Qwen3-4B · S 0.237 · 75.50B · 50.72%Qwen3-4B · S 0.237 · 88.08B · 50.58%Qwen3-4B · S 0.237 · 100.66B · 50.59%Qwen3-4B-Base · S 0.146 · 12.58B · 50.33%Qwen3-4B-Base · S 0.146 · 25.17B · 50.44%Qwen3-4B-Base · S 0.146 · 37.75B · 50.74%Qwen3-4B-Base · S 0.146 · 50.33B · 50.97%Qwen3-4B-Base · S 0.146 · 62.91B · 51.26%Qwen3-4B-Base · S 0.146 · 75.50B · 51.21%Qwen3-4B-Base · S 0.146 · 88.08B · 51.33%Qwen3-4B-Base · S 0.146 · 100.66B · 51.22%deepseek-llm-7b-chat · S -0.175 · 12.58B · 42.47%deepseek-llm-7b-chat · S -0.175 · 25.17B · 43.61%deepseek-llm-7b-chat · S -0.175 · 37.75B · 44.62%deepseek-llm-7b-chat · S -0.175 · 50.33B · 46.72%deepseek-llm-7b-chat · S -0.175 · 62.91B · 47.82%deepseek-llm-7b-chat · S -0.175 · 75.50B · 48.21%deepseek-llm-7b-chat · S -0.175 · 88.08B · 48.55%deepseek-llm-7b-chat · S -0.175 · 100.66B · 48.23%deepseek-llm-7b-base · S -0.096 · 12.58B · 44.17%deepseek-llm-7b-base · S -0.096 · 25.17B · 45.39%deepseek-llm-7b-base · S -0.096 · 37.75B · 47.23%deepseek-llm-7b-base · S -0.096 · 50.33B · 48.22%deepseek-llm-7b-base · S -0.096 · 62.91B · 48.27%deepseek-llm-7b-base · S -0.096 · 75.50B · 48.76%deepseek-llm-7b-base · S -0.096 · 88.08B · 49.11%deepseek-llm-7b-base · S -0.096 · 100.66B · 49.69%deepseek-math-7b-instruct · S -0.215 · 12.58B · 44.34%deepseek-math-7b-instruct · S -0.215 · 25.17B · 44.39%deepseek-math-7b-instruct · S -0.215 · 37.75B · 44.25%deepseek-math-7b-instruct · S -0.215 · 50.33B · 44.70%deepseek-math-7b-instruct · S -0.215 · 62.91B · 45.29%deepseek-math-7b-instruct · S -0.215 · 75.50B · 46.70%deepseek-math-7b-instruct · S -0.215 · 88.08B · 47.64%deepseek-math-7b-instruct · S -0.215 · 100.66B · 48.33%deepseek-math-7b-base · S -0.026 · 12.58B · 43.55%deepseek-math-7b-base · S -0.026 · 25.17B · 44.61%deepseek-math-7b-base · S -0.026 · 37.75B · 45.89%deepseek-math-7b-base · S -0.026 · 50.33B · 46.96%deepseek-math-7b-base · S -0.026 · 62.91B · 47.99%deepseek-math-7b-base · S -0.026 · 75.50B · 48.65%deepseek-math-7b-base · S -0.026 · 88.08B · 49.11%deepseek-math-7b-base · S -0.026 · 100.66B · 48.76%Falcon3-7B-Instruct · S 0.141 · 12.58B · 52.41%Falcon3-7B-Instruct · S 0.141 · 25.17B · 52.23%Falcon3-7B-Instruct · S 0.141 · 37.75B · 52.66%Falcon3-7B-Instruct · S 0.141 · 50.33B · 53.02%Falcon3-7B-Instruct · S 0.141 · 62.91B · 53.50%Falcon3-7B-Instruct · S 0.141 · 75.50B · 53.57%Falcon3-7B-Instruct · S 0.141 · 88.08B · 53.75%Falcon3-7B-Instruct · S 0.141 · 100.66B · 53.97%Falcon3-7B-Base · S 0.096 · 12.58B · 52.22%Falcon3-7B-Base · S 0.096 · 25.17B · 52.08%Falcon3-7B-Base · S 0.096 · 37.75B · 52.17%Falcon3-7B-Base · S 0.096 · 50.33B · 52.37%Falcon3-7B-Base · S 0.096 · 62.91B · 52.76%Falcon3-7B-Base · S 0.096 · 75.50B · 52.79%Falcon3-7B-Base · S 0.096 · 88.08B · 53.08%Falcon3-7B-Base · S 0.096 · 100.66B · 53.11%Mistral-7B-Instruct-v0.3 · S -0.063 · 12.58B · 46.72%Mistral-7B-Instruct-v0.3 · S -0.063 · 25.17B · 47.01%Mistral-7B-Instruct-v0.3 · S -0.063 · 37.75B · 47.39%Mistral-7B-Instruct-v0.3 · S -0.063 · 50.33B · 47.13%Mistral-7B-Instruct-v0.3 · S -0.063 · 62.91B · 46.92%Mistral-7B-Instruct-v0.3 · S -0.063 · 75.50B · 46.92%Mistral-7B-Instruct-v0.3 · S -0.063 · 88.08B · 47.88%Mistral-7B-Instruct-v0.3 · S -0.063 · 100.66B · 48.37%Mistral-7B-v0.3 · S -0.021 · 12.58B · 43.91%Mistral-7B-v0.3 · S -0.021 · 25.17B · 44.72%Mistral-7B-v0.3 · S -0.021 · 37.75B · 45.15%Mistral-7B-v0.3 · S -0.021 · 50.33B · 46.07%Mistral-7B-v0.3 · S -0.021 · 62.91B · 46.00%Mistral-7B-v0.3 · S -0.021 · 75.50B · 46.28%Mistral-7B-v0.3 · S -0.021 · 88.08B · 45.52%Mistral-7B-v0.3 · S -0.021 · 100.66B · 45.22%Qwen3-8B · S 0.339 · 12.58B · 55.06%Qwen3-8B · S 0.339 · 25.17B · 54.67%Qwen3-8B · S 0.339 · 37.75B · 54.88%Qwen3-8B · S 0.339 · 50.33B · 55.73%Qwen3-8B · S 0.339 · 62.91B · 56.58%Qwen3-8B · S 0.339 · 75.50B · 57.43%Qwen3-8B · S 0.339 · 88.08B · 57.65%Qwen3-8B · S 0.339 · 100.66B · 58.26%Qwen3-8B-Base · S 0.260 · 12.58B · 54.56%Qwen3-8B-Base · S 0.260 · 25.17B · 54.42%Qwen3-8B-Base · S 0.260 · 37.75B · 54.66%Qwen3-8B-Base · S 0.260 · 50.33B · 54.73%Qwen3-8B-Base · S 0.260 · 62.91B · 54.81%Qwen3-8B-Base · S 0.260 · 75.50B · 54.86%Qwen3-8B-Base · S 0.260 · 88.08B · 54.74%Qwen3-8B-Base · S 0.260 · 100.66B · 54.94%gemma-2-9b-it · S 0.188 · 12.58B · 53.54%gemma-2-9b-it · S 0.188 · 25.17B · 53.71%gemma-2-9b-it · S 0.188 · 37.75B · 54.03%gemma-2-9b-it · S 0.188 · 50.33B · 54.12%gemma-2-9b-it · S 0.188 · 62.91B · 54.29%gemma-2-9b-it · S 0.188 · 75.50B · 54.72%gemma-2-9b-it · S 0.188 · 88.08B · 54.97%gemma-2-9b-it · S 0.188 · 100.66B · 55.19%gemma-2-9b · S 0.274 · 12.58B · 50.89%gemma-2-9b · S 0.274 · 25.17B · 51.57%gemma-2-9b · S 0.274 · 37.75B · 52.59%gemma-2-9b · S 0.274 · 50.33B · 52.82%gemma-2-9b · S 0.274 · 62.91B · 53.08%gemma-2-9b · S 0.274 · 75.50B · 53.43%gemma-2-9b · S 0.274 · 88.08B · 54.20%gemma-2-9b · S 0.274 · 100.66B · 54.44%Falcon3-10B-Instruct · S 0.251 · 12.58B · 54.28%Falcon3-10B-Instruct · S 0.251 · 25.17B · 54.65%Falcon3-10B-Instruct · S 0.251 · 37.75B · 55.78%Falcon3-10B-Instruct · S 0.251 · 50.33B · 55.88%Falcon3-10B-Instruct · S 0.251 · 62.91B · 56.23%Falcon3-10B-Instruct · S 0.251 · 75.50B · 56.30%Falcon3-10B-Instruct · S 0.251 · 88.08B · 56.44%Falcon3-10B-Instruct · S 0.251 · 100.66B · 56.43%Falcon3-10B-Base · S 0.186 · 12.58B · 52.53%Falcon3-10B-Base · S 0.186 · 25.17B · 52.14%Falcon3-10B-Base · S 0.186 · 37.75B · 52.71%Falcon3-10B-Base · S 0.186 · 50.33B · 53.23%Falcon3-10B-Base · S 0.186 · 62.91B · 54.27%Falcon3-10B-Base · S 0.186 · 75.50B · 54.23%Falcon3-10B-Base · S 0.186 · 88.08B · 54.15%Falcon3-10B-Base · S 0.186 · 100.66B · 53.99%Qwen3-30B-A3B · S 0.470 · 12.58B · 59.28%Qwen3-30B-A3B · S 0.470 · 25.17B · 59.76%Qwen3-30B-A3B · S 0.470 · 37.75B · 60.45%Qwen3-30B-A3B · S 0.470 · 50.33B · 60.78%Qwen3-30B-A3B · S 0.470 · 62.91B · 61.07%Qwen3-30B-A3B · S 0.470 · 75.50B · 61.81%Qwen3-30B-A3B · S 0.470 · 88.08B · 62.38%Qwen3-30B-A3B · S 0.470 · 100.66B · 62.77%Qwen3-30B-A3B-Base · S 0.444 · 12.58B · 55.32%Qwen3-30B-A3B-Base · S 0.444 · 25.17B · 55.82%Qwen3-30B-A3B-Base · S 0.444 · 37.75B · 56.92%Qwen3-30B-A3B-Base · S 0.444 · 50.33B · 57.94%Qwen3-30B-A3B-Base · S 0.444 · 62.91B · 59.12%Qwen3-30B-A3B-Base · S 0.444 · 75.50B · 60.03%Qwen3-30B-A3B-Base · S 0.444 · 88.08B · 60.33%Qwen3-30B-A3B-Base · S 0.444 · 100.66B · 60.32%
Hover or focus a checkpointColored: selected for fitting · gray: excluded · coral: original 72B holdouts

The horizontal axis is ÂS + B̂ ln D, where B̂ = B₀ − BₘS. P₀ is excluded from the horizontal coordinate but remains in the fit; the reference line is y = x + P₀.

Live coefficients 0.2340B₀ 0.0154Bₘ 0.0092P₀ 0.4340
How this interactive fit relates to the notebook

Real observations come from the supplied text_accuracy.csv and multimodal_accuracy.csv: 32 backbones × 8 checkpoints, plus two 72B holdouts × 4 checkpoints. Tokens = checkpoint step × 8,192 × 512 / 10⁹.

The PCA mean, 12 components (≥95% variance), and normalized capability direction are recovered from the notebook’s original 32-model training pool and saved weights. They remain fixed during interaction. Your filters refit Â, B₀, Bₘ and P₀ with constrained least squares, enforcing nonnegative Â, Bₘ and absorption across the selected training S range. The notebook’s Huber δ = 1 objective is quadratic for these accuracy residuals, but the browser does not rerun its joint weight learning, regularization, Differential Evolution or L-BFGS-B.

The default all-32 fit is recovered from rounded saved notebook weights, so small differences from the paper are expected. Removing a training model or family here excludes its observations only from the coefficient refit; it is not a new independent leave-one-family-out experiment because S was originally learned from all 32 backbones.

03The evidence

One law. Unseen scales and families.

A controlled training recipe isolates the effect of the language backbone.

ArchitectureLLaVA-OneVision + SigLIP
Training dataInfinity-MM · two-stage alignment
Prediction inputs / target40 filtered text / 35 multimodal benchmarks
Cross-backbone fit · §3.4

A shared predictor
across 32 backbones.

1.287%

Mean absolute error in multimodal accuracy, without family-specific recalibration.

The fitting pool includes 32 backbones. Qwen2.5-72B Base and Instruct are held out, bringing the full study to 34.
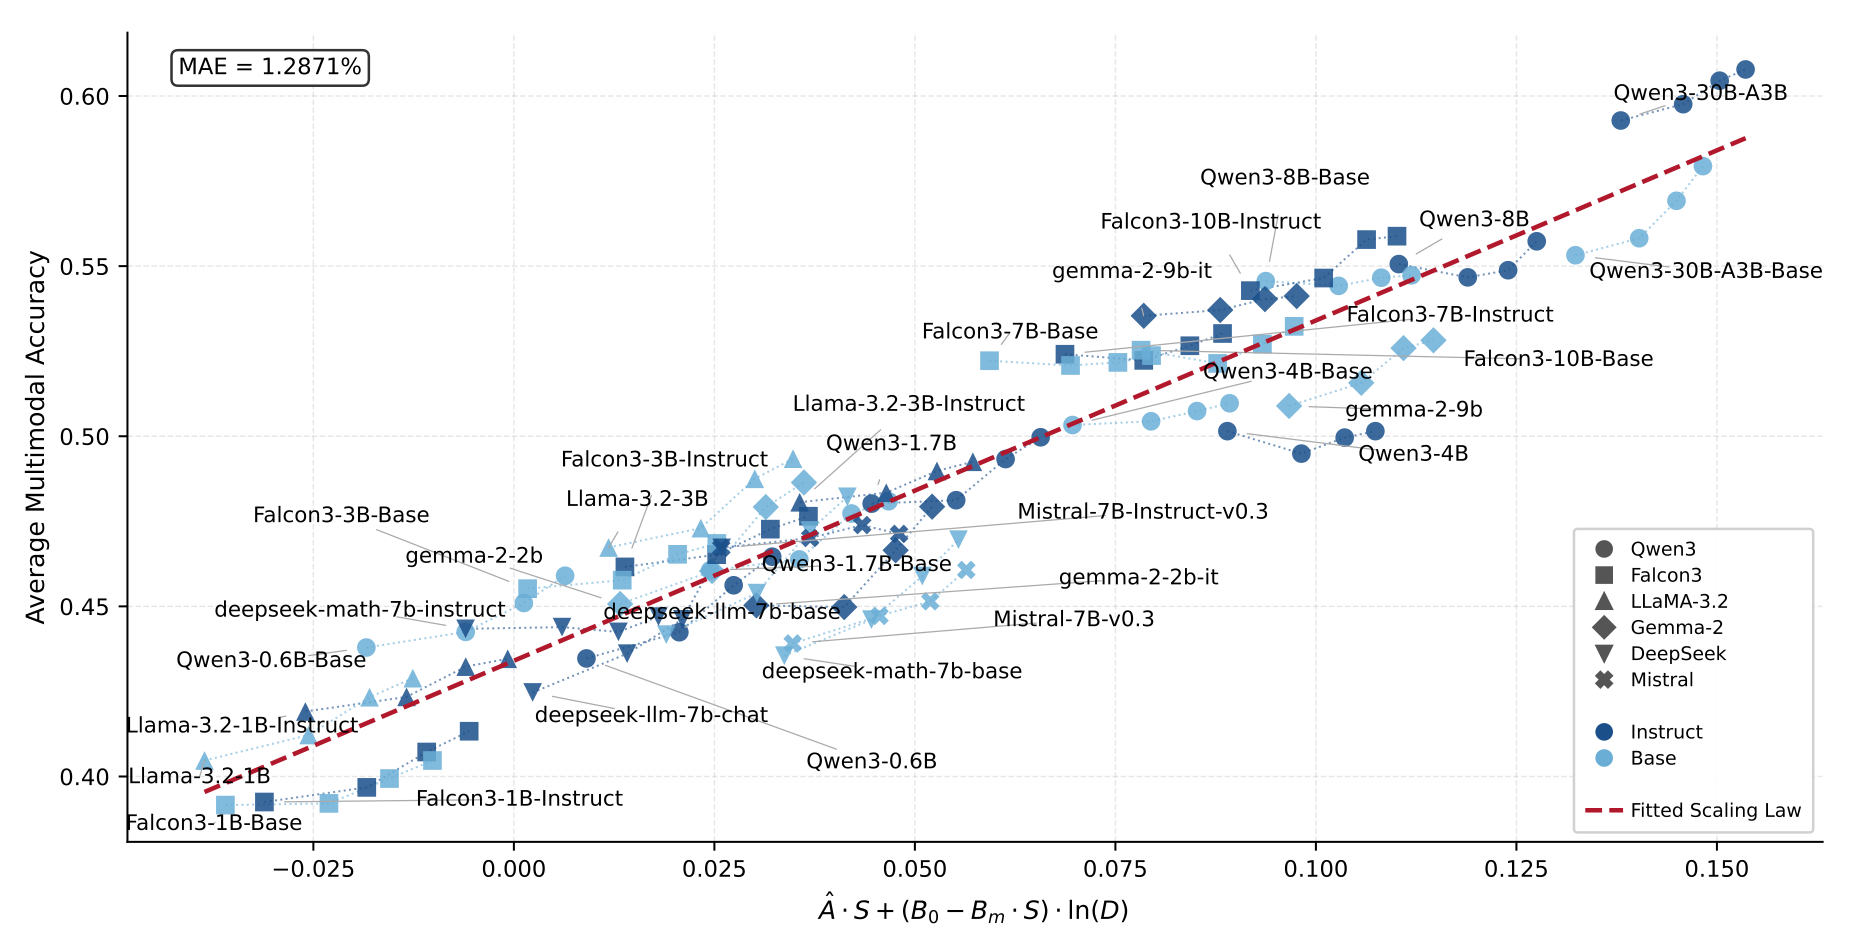
Multimodal accuracy of 32 language backbones plotted against the capability and data composite metric, closely following a single fitted line.
Figure 2 · Accuracy fit Each point is a checkpoint; marker shapes indicate families and color distinguishes Base / Instruct. Click the figure to enlarge ↗
72B scale extrapolation

Predict beyond the fitting scale.

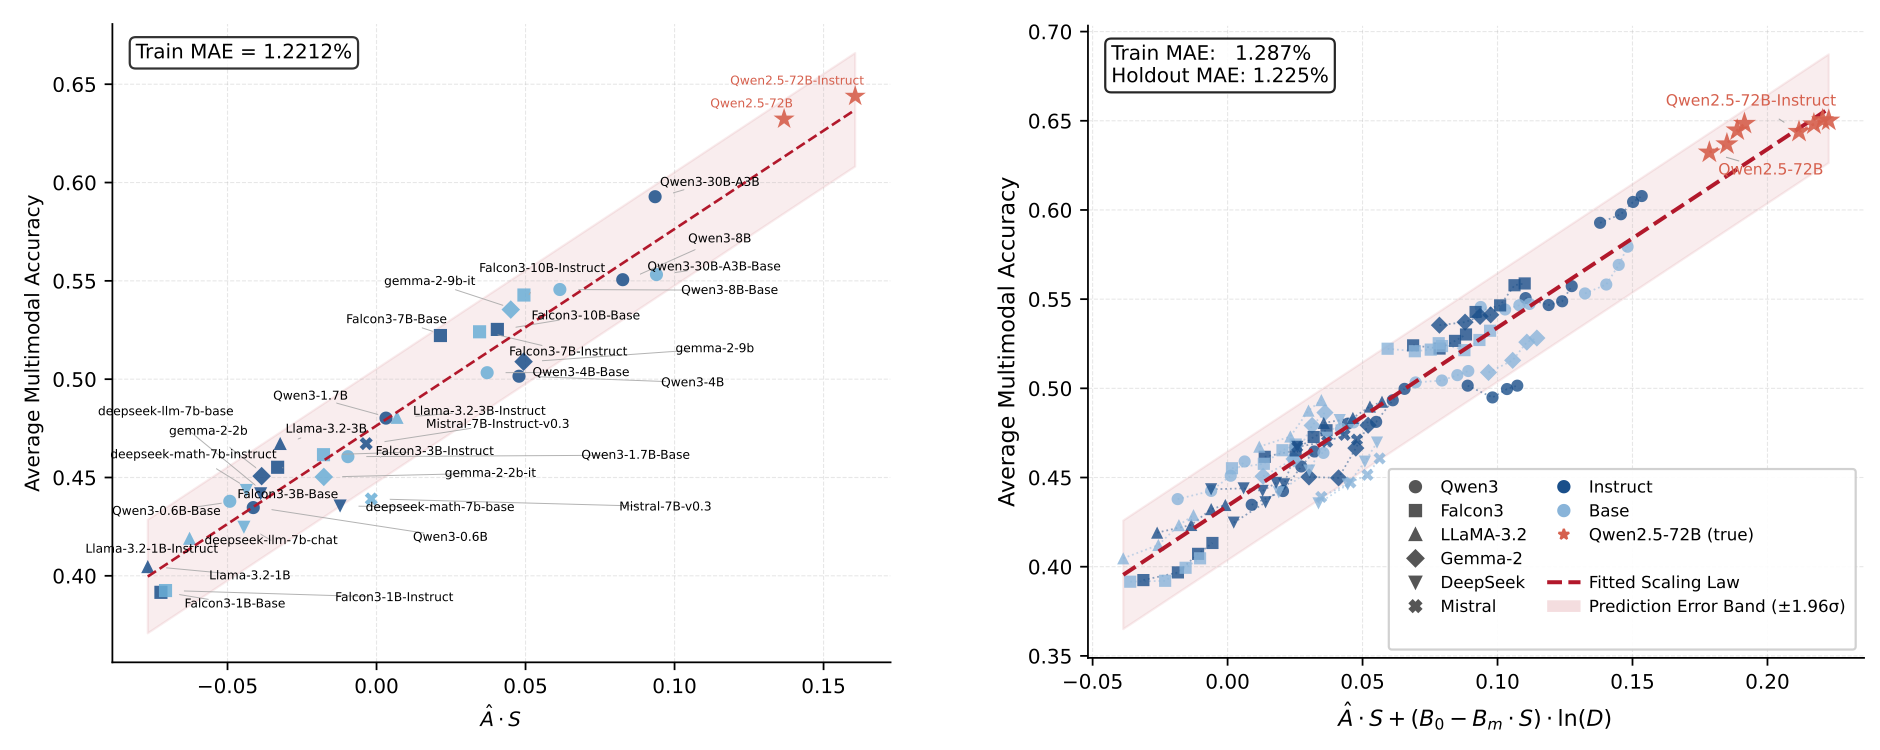
1.92%

Base transfer error

0.70%

Instruct transfer error

1.225%

Full trajectory MAE (Figure 3b)

Qwen2.5-72B held-out checkpoints and predicted accuracy bands at the starting budget and across the full training trajectory.
Figure 3 · Transfer & absorption Qwen2.5-72B Base and Instruct test both the initial transfer term and full trajectory prediction, with a combined holdout MAE of 1.225% across the full trajectories (panel b). Click the figure to enlarge ↗
Leave one family out · §3.5

Entirely new families.
Consistent scaling trends.

Fit on the remaining families, then predict all trajectories of the held-out family.
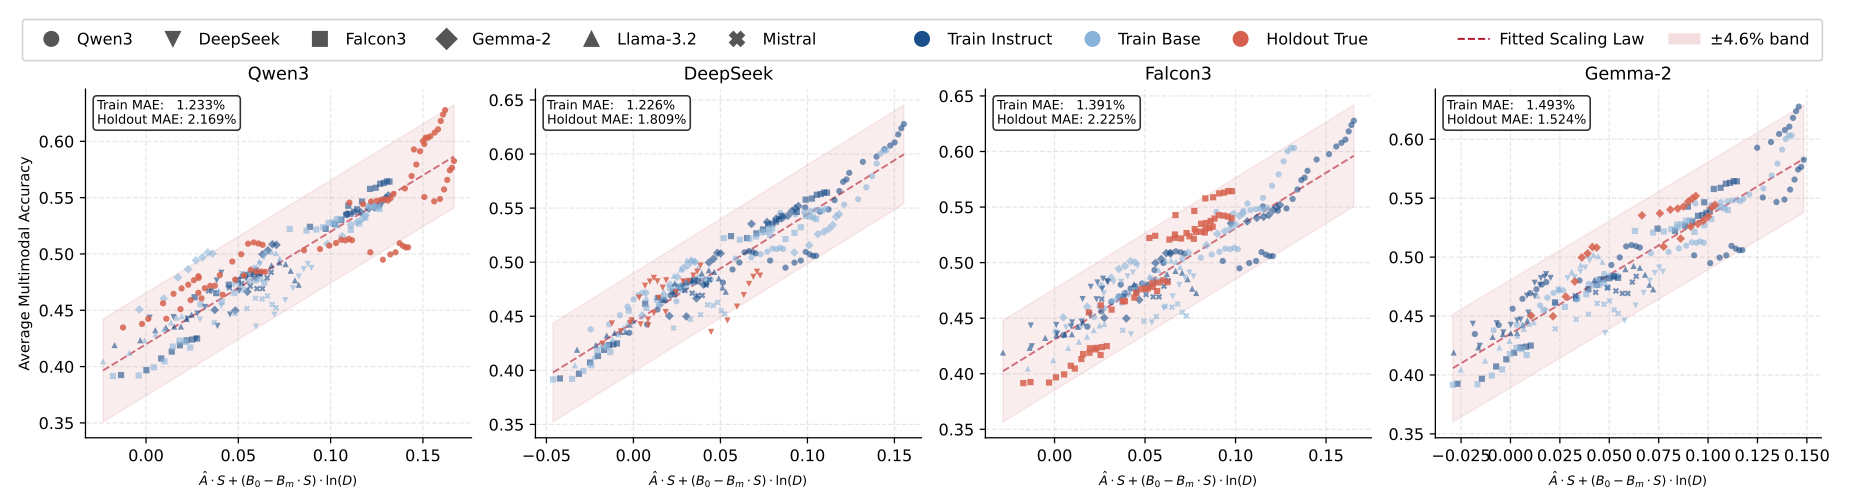
Qwen3
2.169%
DeepSeek
1.809%
Falcon3
2.225%
Gemma-2
1.524%
Held-out accuracy MAE · lower is better · Figure 4
Four leave-one-family-out fits for Qwen3, DeepSeek, Falcon3 and Gemma-2, showing predicted versus observed multimodal accuracy.
Figure 4 · Cross-family generalization The global trend generalizes across architectural and pretraining differences. Click the figure to enlarge ↗
04Transfer dynamics

What the coefficients reveal.

Text capability is multidimensional. More of it does not always transfer in the same way.

Finding 01

Some text benchmarks
impose a transfer tax.

Benchmark-level coefficients reveal positive and negative associations with multimodal performance. Unweighted text leaderboard averages can reward dimensions that transfer poorly.

25stable positive
6stable negative
9unstable

These counts summarize sign stability across six robustness refits, with at least five consistent signs required for a stable classification (Appendix I). They are distinct from the individual main-fit coefficients shown in the bar chart.

Selected main-fit transfer coefficients Table 7 · λ · one fitted model
dyck_languages_hard
+0.119
hindu_knowledge
+0.108
mmlu_stem
+0.057
matrixshapes
+0.049
boolean_expressions_hard
-0.078
contextual_param_knowledge_conflicts
-0.048
entailed_polarity
-0.037
multirc
-0.035
← Transfer taxPositive transfer →

A negative main-fit coefficient does not imply a stable transfer tax across refits. For example, boolean_expressions_hard is negative here but classified as unstable in Appendix I. Coefficients describe fitted associations, rather than causal effects.

Finding 02

Instruction tuning starts ahead.
Base models scale further.

Instruct backbones have a higher fitted transfer coefficient, but their absorption-decay coefficient Bₘ is approximately 1.33× that of Base backbones (0.0104 vs. 0.0078). In B̂ = B₀ − BₘS, this means absorption decreases more steeply as text capability S increases. Base models have a larger average absorption rate and can overtake at larger data budgets.

This is an aggregate tendency, with family-specific exceptions. Among pairs with positive slope differences, the median estimated crossover is ≈141B multimodal tokens (Appendix J).

Base vs. Instruct · Table 2
Fitted parameterBaseInstruct
Transfer · Â0.2120.254
Absorption decay · Bₘ0.00780.0104
Mean absorption · B̄0.01610.0147
Choose the backbone together with the data budget.
Finding 03

Families occupy different transfer–absorption regimes.

Family-specific fits · Table 3 · absorption values in original units
Model familyTransfer · ÂAbsorption decay · BₘMean absorption · B̄
Llama0.3610.04550.0122
Gemma-20.3240.04510.0213
Falcon30.2880.01330.0117
Qwen30.2460.02190.0126

Llama has the highest transfer slope and fastest absorption decay; Gemma-2 has the highest mean absorption. Backbone choice depends on the intended training regime.

05Practical use

From predicting performance to planning training.

The same metric guides
batch-size extrapolation.

A controlled sweep of five backbones and five batch sizes (128–2,048) finds that the optimal batch size increases with the composite capability–data metric.

Qwen3-1.7B prefers a larger batch than Falcon3-3B, reversing their parameter-count ordering.

2,66372B Base
4,19472B Instruct

Predicted optimal batch sizes for Qwen2.5-72B at 50B tokens (§4.4). These are extrapolations, not measured sweep optima.
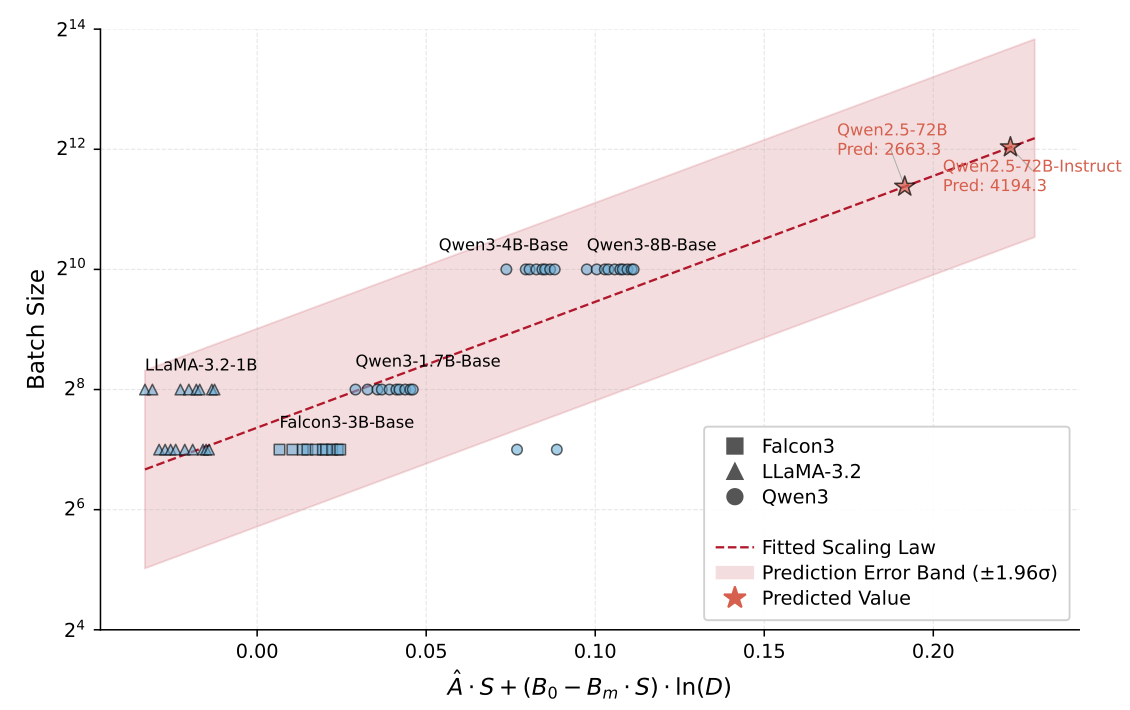
Optimal batch size increases with the composite capability and data metric, with predicted values for Qwen2.5-72B at 50 billion tokens.
Figure 5 · Batch-size extrapolation Capability and data jointly inform training configuration. Click the figure to enlarge ↗
Scope and limitations

The law is validated under a unified LLaVA-OneVision late-fusion recipe with a fixed SigLIP vision encoder. Generalization to early-fusion or native multimodal architectures, other training recipes, and jointly scaled vision encoders remains future work.

The takeaway

Choose by capability.
Plan for the data.

A quantitative bridge from language backbones
to multimodal learning.

Build on this work

Citation

If you find this work useful, please cite our paper.

BibTeX
@misc{li2026transferstextvision,
  title={What Transfers from Text to Vision? Capability Scaling Laws and Transfer Dynamics for VLMs},
  author={Ziran Li and Qiang Wang and Zhengyu Chen and Shanglin Lei and Borun Chen and Jingang Wang and Xunliang Cai},
  year={2026},
  eprint={2608.00013},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2608.00013}
}